
When the Intelligence Is Wrong Before Anyone Fires a Shot
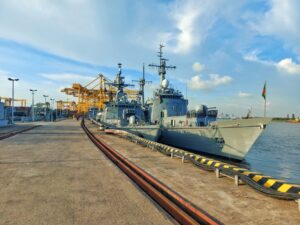
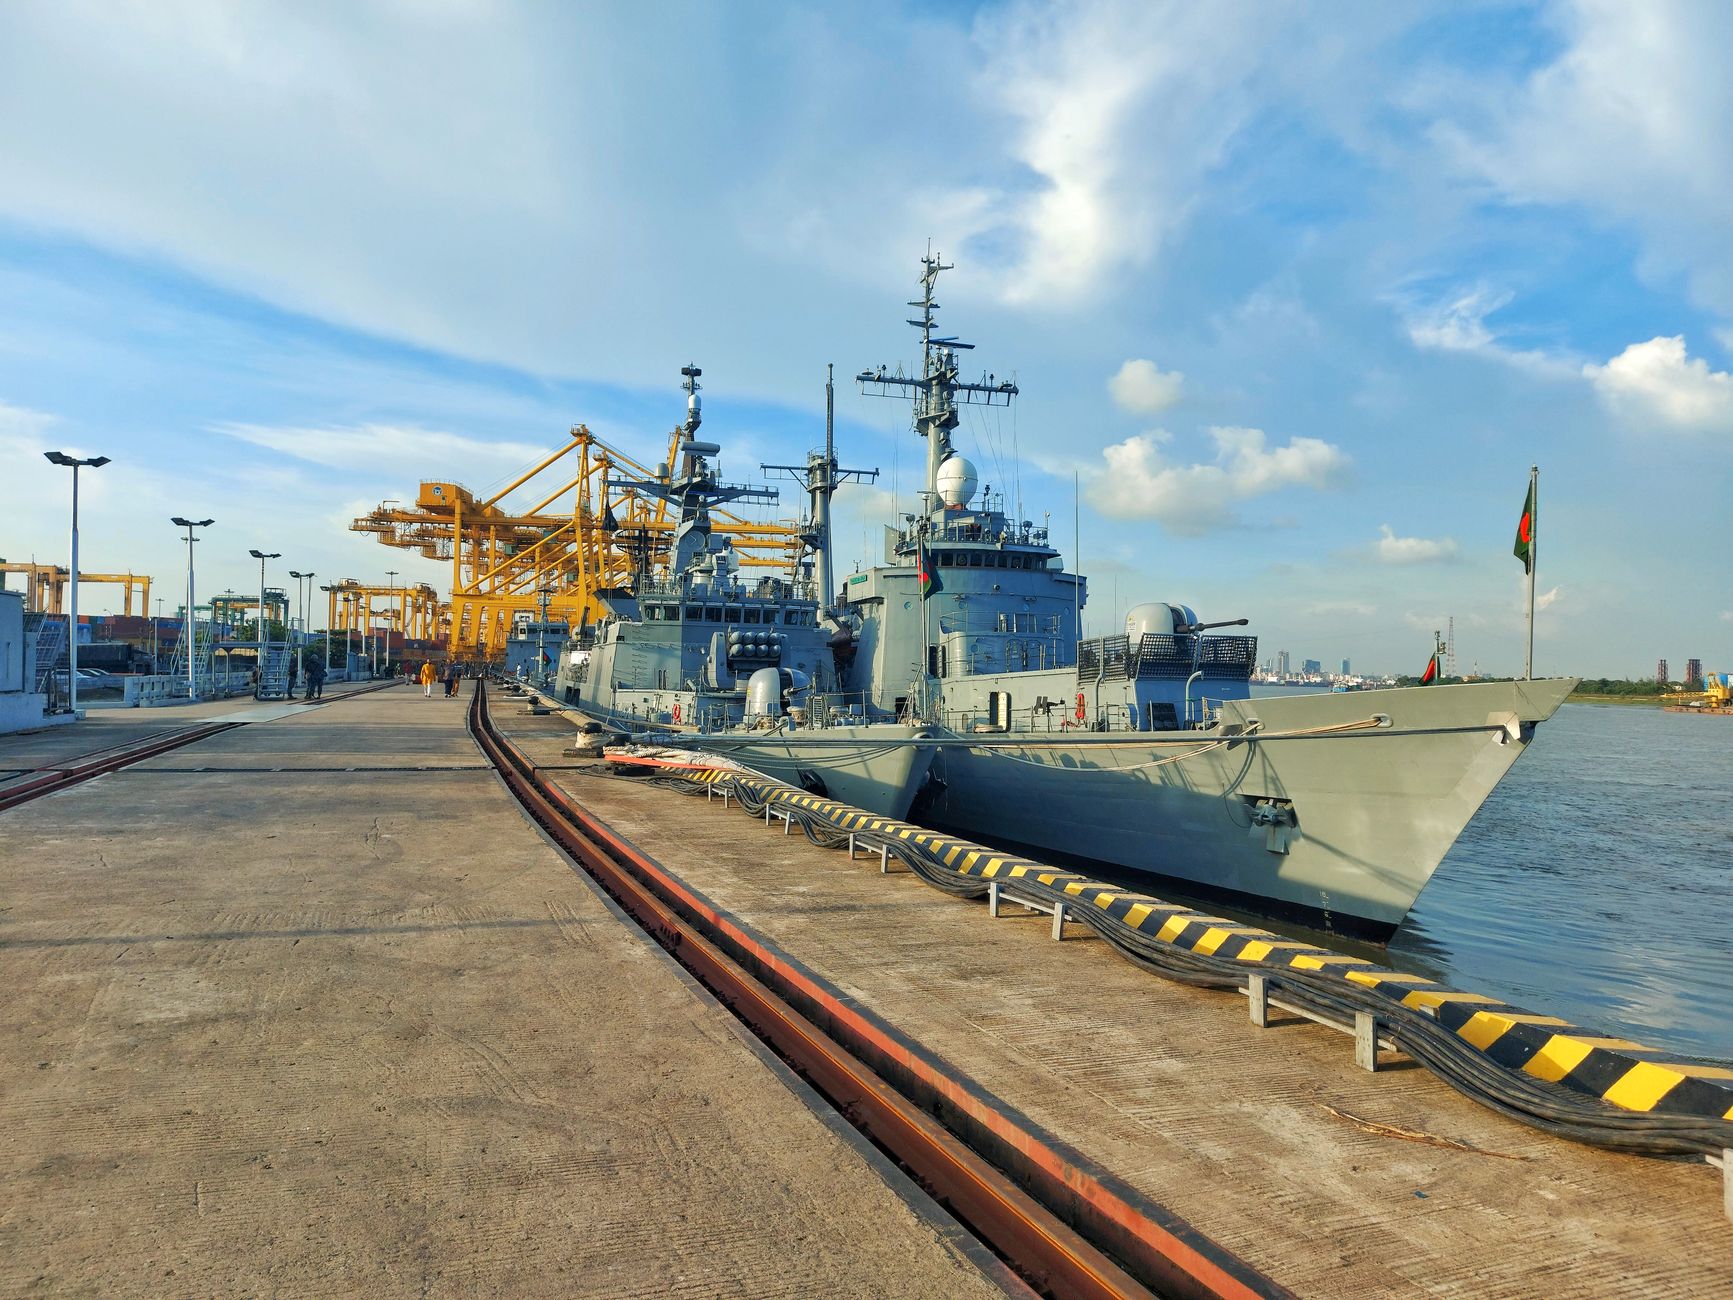
A US military operation against a Chinese vessel in the Middle East came close to happening – not because of confirmed intelligence, but because an AI chatbot got the facts completely wrong. According to a CNN report citing four sources familiar with the episode, a US Special Operations Command analyst submitted an intelligence report claiming a Chinese ship was carrying nuclear arms program components. That report was, by the account of those sources, “entirely false.”
The US military had already begun preparing to intercept and board the vessel, with air support lined up, before someone caught the error.
One source described the incident to CNN in stark terms: the AI-powered mistake “almost started a war.” The chatbot used in generating the report had “inaccurately identified the material the ship was carrying” – a failure that, in any other context, might have been an embarrassing bug report. In this context, it nearly triggered an armed confrontation between two nuclear-armed states.
How a Hallucination Moves Through a Military Pipeline
The term “hallucination” has become a standard part of the AI industry’s vocabulary – shorthand for when a language model generates confident-sounding information that has no basis in reality. For most users, that means a chatbot inventing a book citation or misremembering a date. For a Special Operations Command analyst working on threat assessments, it meant a fabricated cargo manifest that nearly justified a military boarding operation in international waters.
What makes this episode worth examining closely is not just the error itself but how far it traveled before anyone stopped it. The report moved from the analyst through enough of the military decision-making chain that air support was being arranged. The hallucinated intelligence wasn’t flagged at the point of generation, nor at the point of submission, nor apparently at several points after that. It required officials to go back and specifically discover that the chatbot had produced false information before the operation was called off.
That gap – between AI output and human verification – is where the real danger sits. AI tools used in intelligence work aren’t operating inside a sandbox where mistakes are low-stakes. They’re feeding into systems where the outputs carry authority, and where speed is often treated as an asset. When an analyst submits a report, the assumption downstream is generally that the work has been checked. When part of that work was generated by a language model prone to confabulation, that assumption becomes a liability.
The Specific Problem with High-Stakes AI Deployment
The US military has been accelerating its adoption of AI tools across a range of functions, from logistics to intelligence analysis. The argument for doing so is straightforward: AI can process more information faster than human analysts, identify patterns across large datasets, and reduce workload in understaffed units. Those benefits are real. So is the failure mode on display here.
Language models generate text by predicting likely sequences of words based on training data. They do not verify claims against reality before producing them. When a model is asked to analyze intelligence inputs and produce a summary or assessment, it will produce one – and it will produce it with the same syntactic confidence whether the underlying inference is sound or invented. There is no internal alarm that fires when a model crosses from analysis into fabrication. The output looks the same either way.
Deploying that kind of tool inside an intelligence workflow, without a verification layer robust enough to catch wholesale fabrications before they reach decision-makers, produces exactly the scenario CNN described. The Chinese ship was not carrying nuclear arms program components. The US military nearly boarded it anyway. The only thing that prevented it was someone, at some point in the chain, going back to check the source material – a step that apparently took long enough that air support was already being staged.
The Version of This Story Where No One Catches the Error
There is an ongoing institutional argument about how to responsibly integrate AI into military and intelligence operations, and this incident will almost certainly become part of that conversation. The political pressure on US science and defense budgets already shapes how agencies prioritize technology adoption – and cutting corners on verification infrastructure is exactly the kind of decision that happens quietly, under resource constraints, before an incident makes it visible.
What the CNN report leaves unanswered is whether any formal review followed, whether the analyst’s workflow changed, or whether the specific chatbot involved was pulled from use. Four anonymous sources confirmed the episode happened. The structural response to it remains unclear.
The version of this story where nobody catches the hallucination in time doesn’t end with a retraction. It ends somewhere considerably worse – and the gap between the two versions was, by all accounts, narrower than it should have been.